Algorithmic Trading
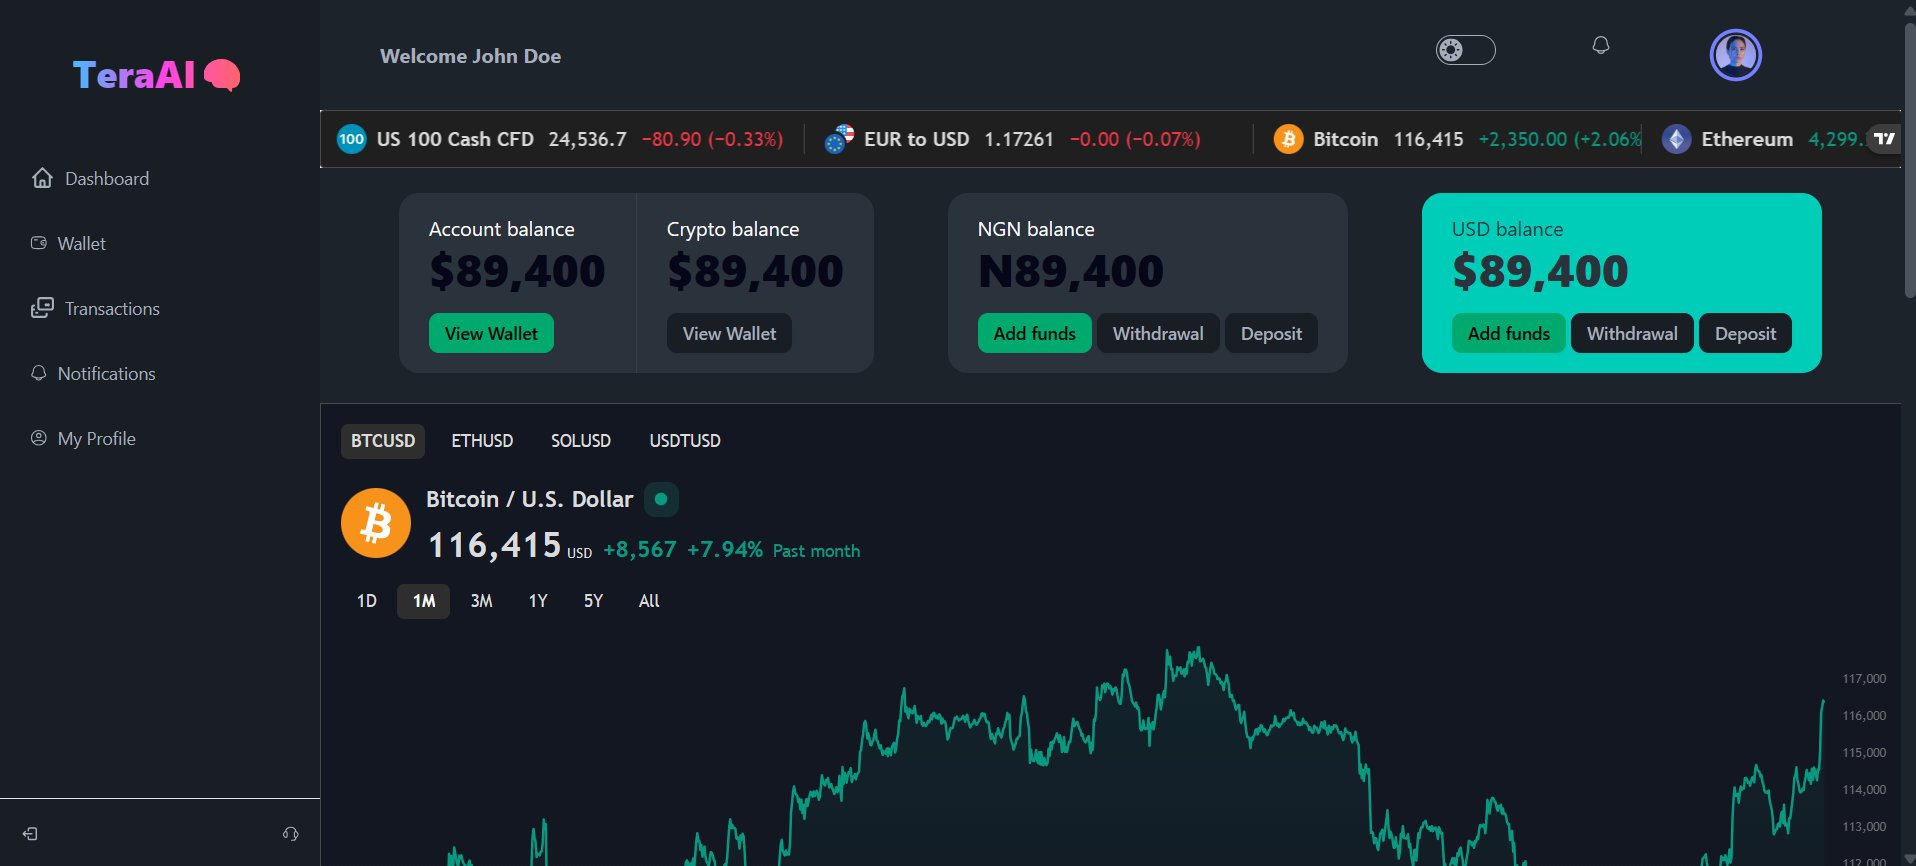
TeraAI PPO Research
I implemented a Gymnasium environment that turns historical market observations and policy actions into simulated trades, with position accounting and slippage. I trained a Stable-Baselines3 PPO policy and replayed its decisions in an offline backtest.
How it’s built View architectureHow it’s built
TeraAI PPO Research · Reinforcement learning trading research with a custom Gymnasium market simulator
TeraAI PPO Research is a reinforcement learning project for training and backtesting a single-asset trading policy offline. I wrote a 492-line Gymnasium environment with a continuous target-exposure action, spread and volume-based slippage, commissions, leverage, margin calls and financing costs, then trained Stable-Baselines3 PPO on daily AAPL data with 7 indicator features. A Streamlit app runs training, backtests and paper-trading connections to Alpaca and Binance through CCXT.
- observation dimensions (50-step window x 7 features + 4 portfolio stats)
- 354
- continuous action: target exposure in [-1, 1]
- 1
- PPO training timesteps
- 300,000
- saved PPO model checkpoints
- 6
- lines of Python
- 1,734
- broker integrations (Alpaca, CCXT)
- 2
Technology and what it does here
- Gymnasium
- Custom TradingEnv with Box observation and action spaces
- Stable-Baselines3 PPO
- MlpPolicy, lr 3e-4, gamma 0.99, GAE 0.95, batch 256, ent_coef 0.005
- PyTorch
- Backend for the Stable-Baselines3 policy network
- yfinance
- Downloads auto-adjusted daily OHLCV data
- pandas-ta
- RSI, MACD, ATR, Bollinger width and OBV indicators
- TensorBoard
- PPO training logs and EvalCallback results
- Streamlit
- Dashboard, backtest, live trading and model training screens
- Plotly
- Equity curve and trade marker charts
- alpaca-trade-api
- Paper account, orders, positions and price data
- CCXT
- Binance balance and market or limit orders
Implementation details
- Execution price applies half the spread plus slippage of slippage_coeff * (volume_ratio^1.2) * price, and fills are capped at volume_limit times the 20-bar average volume.
- Position accounting tracks a weighted average entry price and realises PnL on partial reductions and on crossing through zero to the opposite side.
- Reward is log(net worth change) minus drawdown, turnover and financing penalties, and a maintenance-margin breach force-liquidates the position and ends the episode.
- Backtests report Sharpe ratio, maximum drawdown and CAGR.
Research architecture
This offline experiment uses historical market data to train and replay a trading policy inside a simulated market.
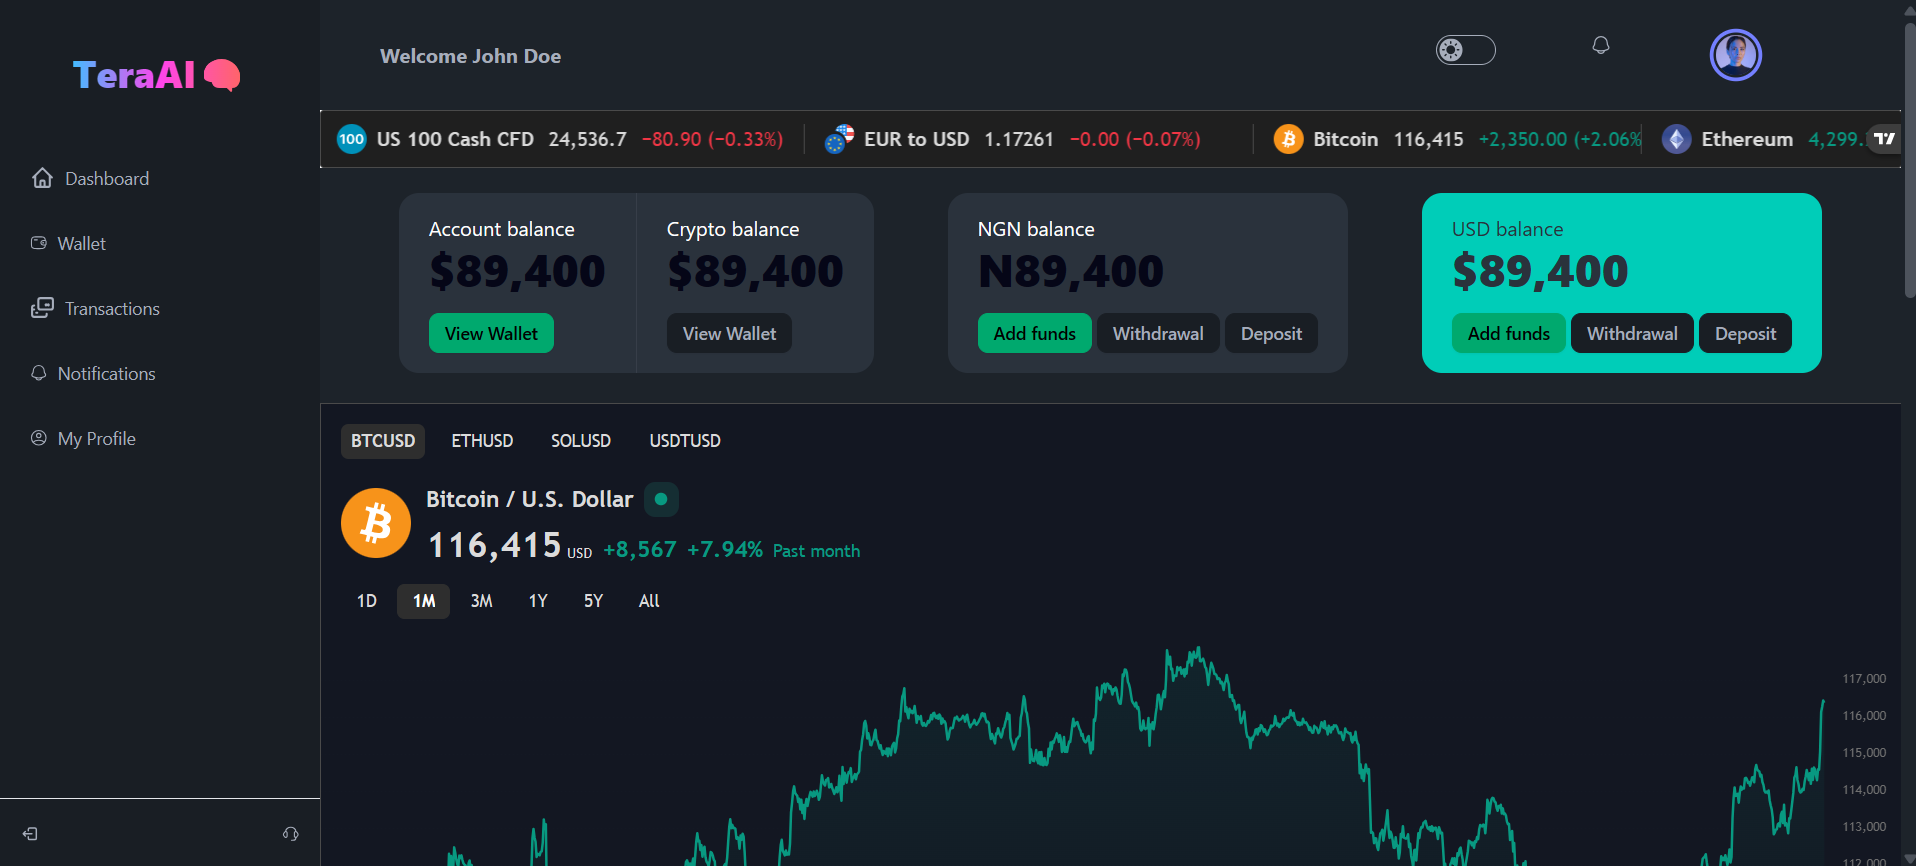
Product screenshot
 Full size
Technologies
- Python
- Gymnasium
- Stable-Baselines3
- PPO